How to create and run a dataset using the API
Using the API has some benefits.
- We can avoid loading all databases and schemas. This can be useful for connecting with a large number of databases.
- The process can be automatized.
- Configuration can be reused easily.
- It is easy to test it.
For creating a job, please, follow these steps.
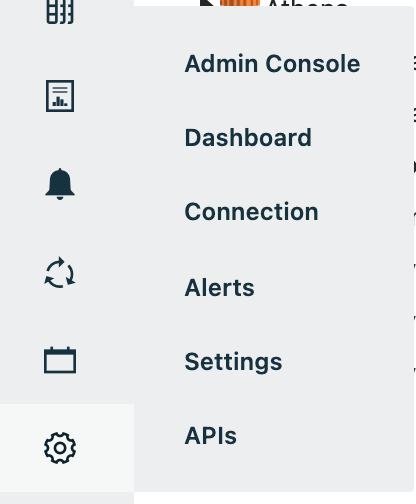
- Access to Admin -> APIs
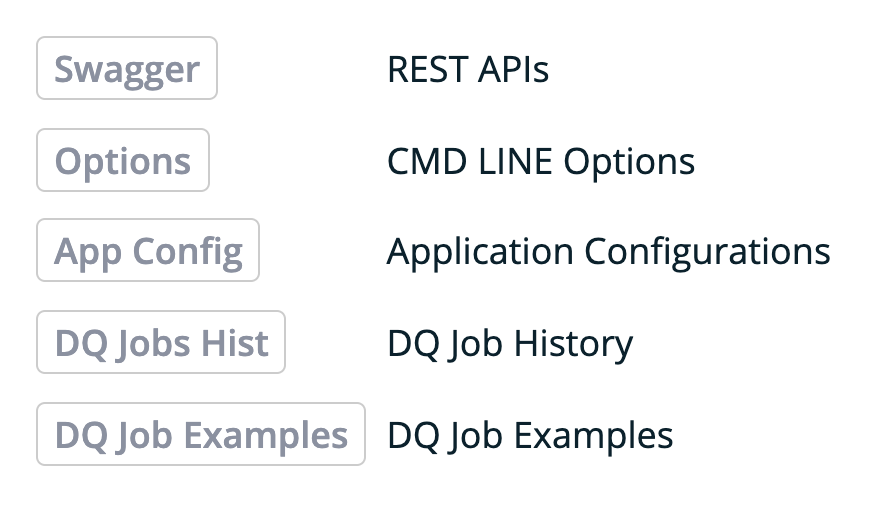
- Click on Rest APIs
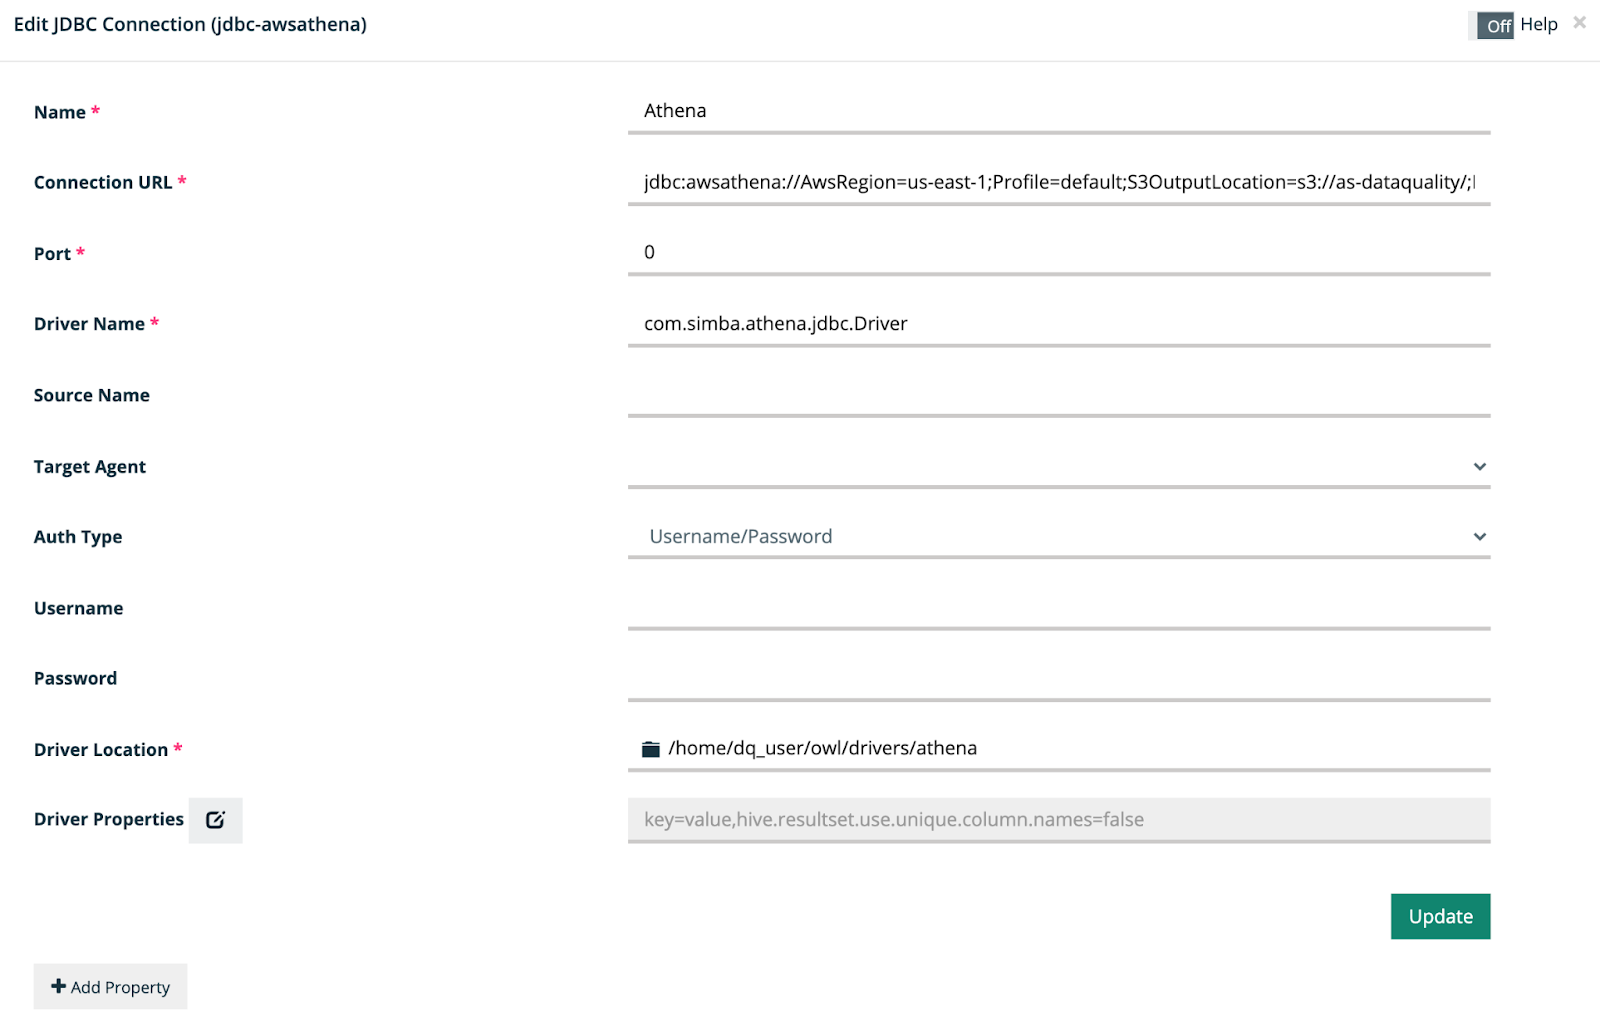
- Go to “Connection” or “Connect to Data” to configure your Athena connection (We did that before). The name of my connection is “Athena”.
- Go to the API and click on the method “/v3/datasetDefs”
- In this method, you can see an example of the schema that we have to complete to be able to create the dataset.
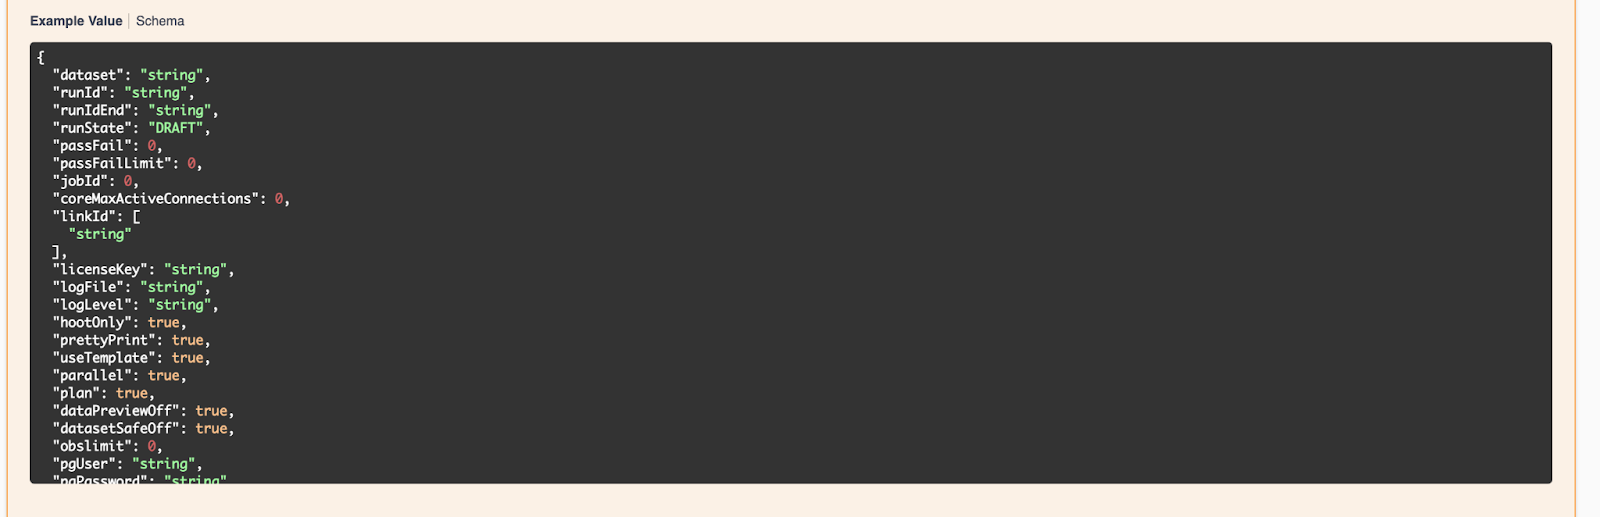
To do the process easy, at the end of the document, you have the complete configuration of this example. This document will show the partes that you have to change. If you have added additional configuration, you have to provide it in the schema too.
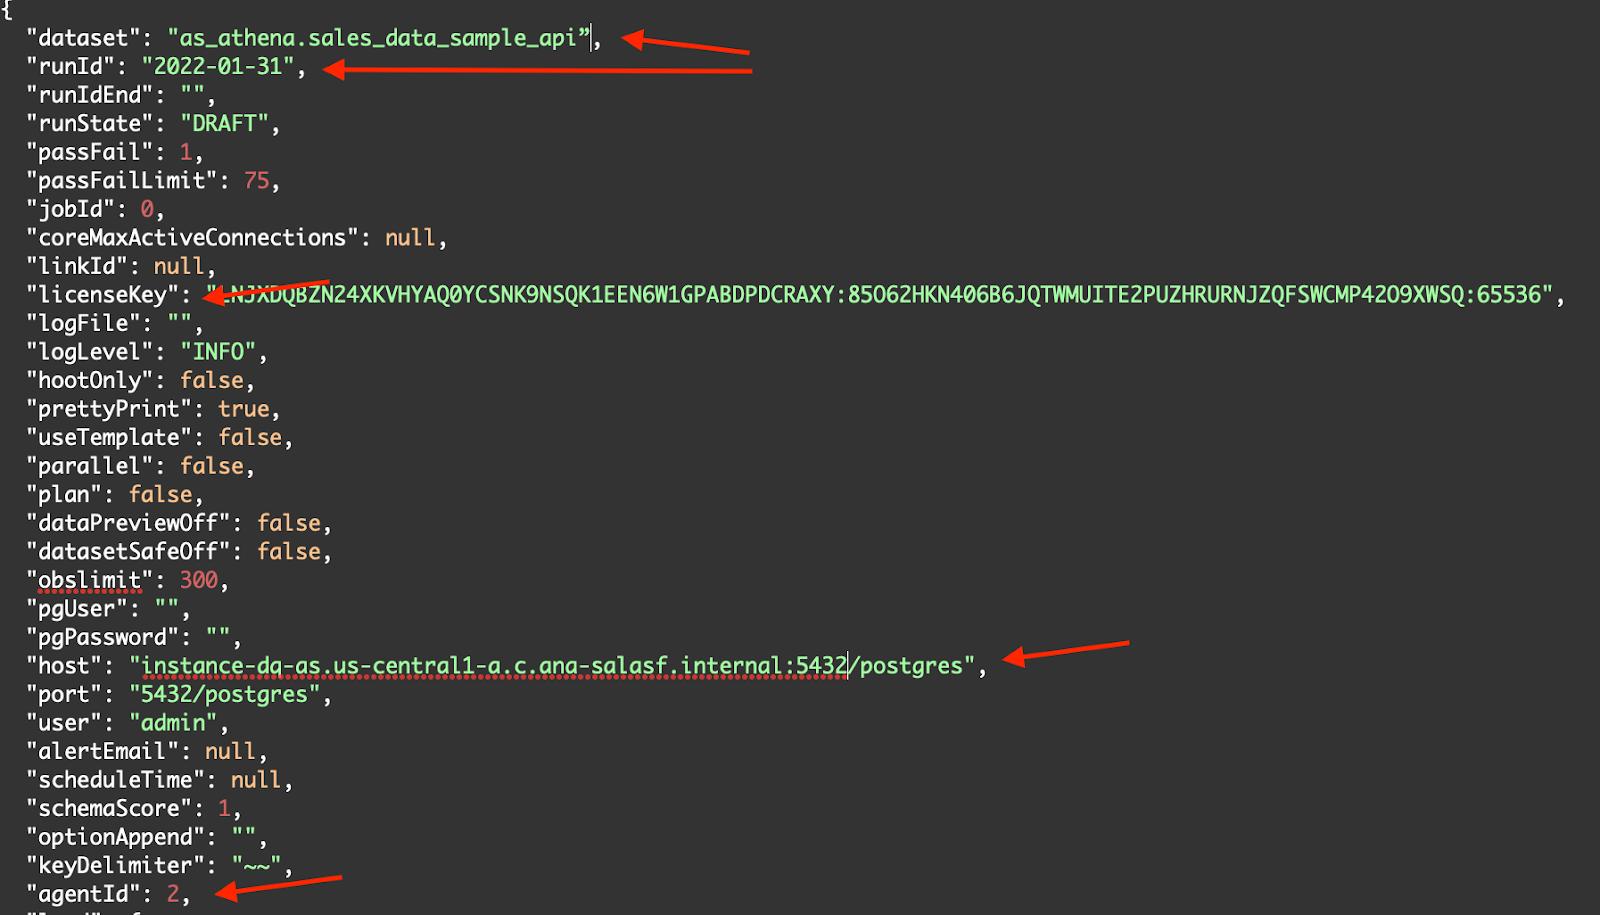
The following fields have to be modified:
-
dataset: The name of the dataset.
-
runID: The date.
-
licenceKey: You licenseKey.
-
host: This is your connection to the metastore.
-
agentId: Usually this value is 2, but in your case, if you have another ID, you have to change this too. To check this, go to Admin console-> Remote Agent and you have the ID.
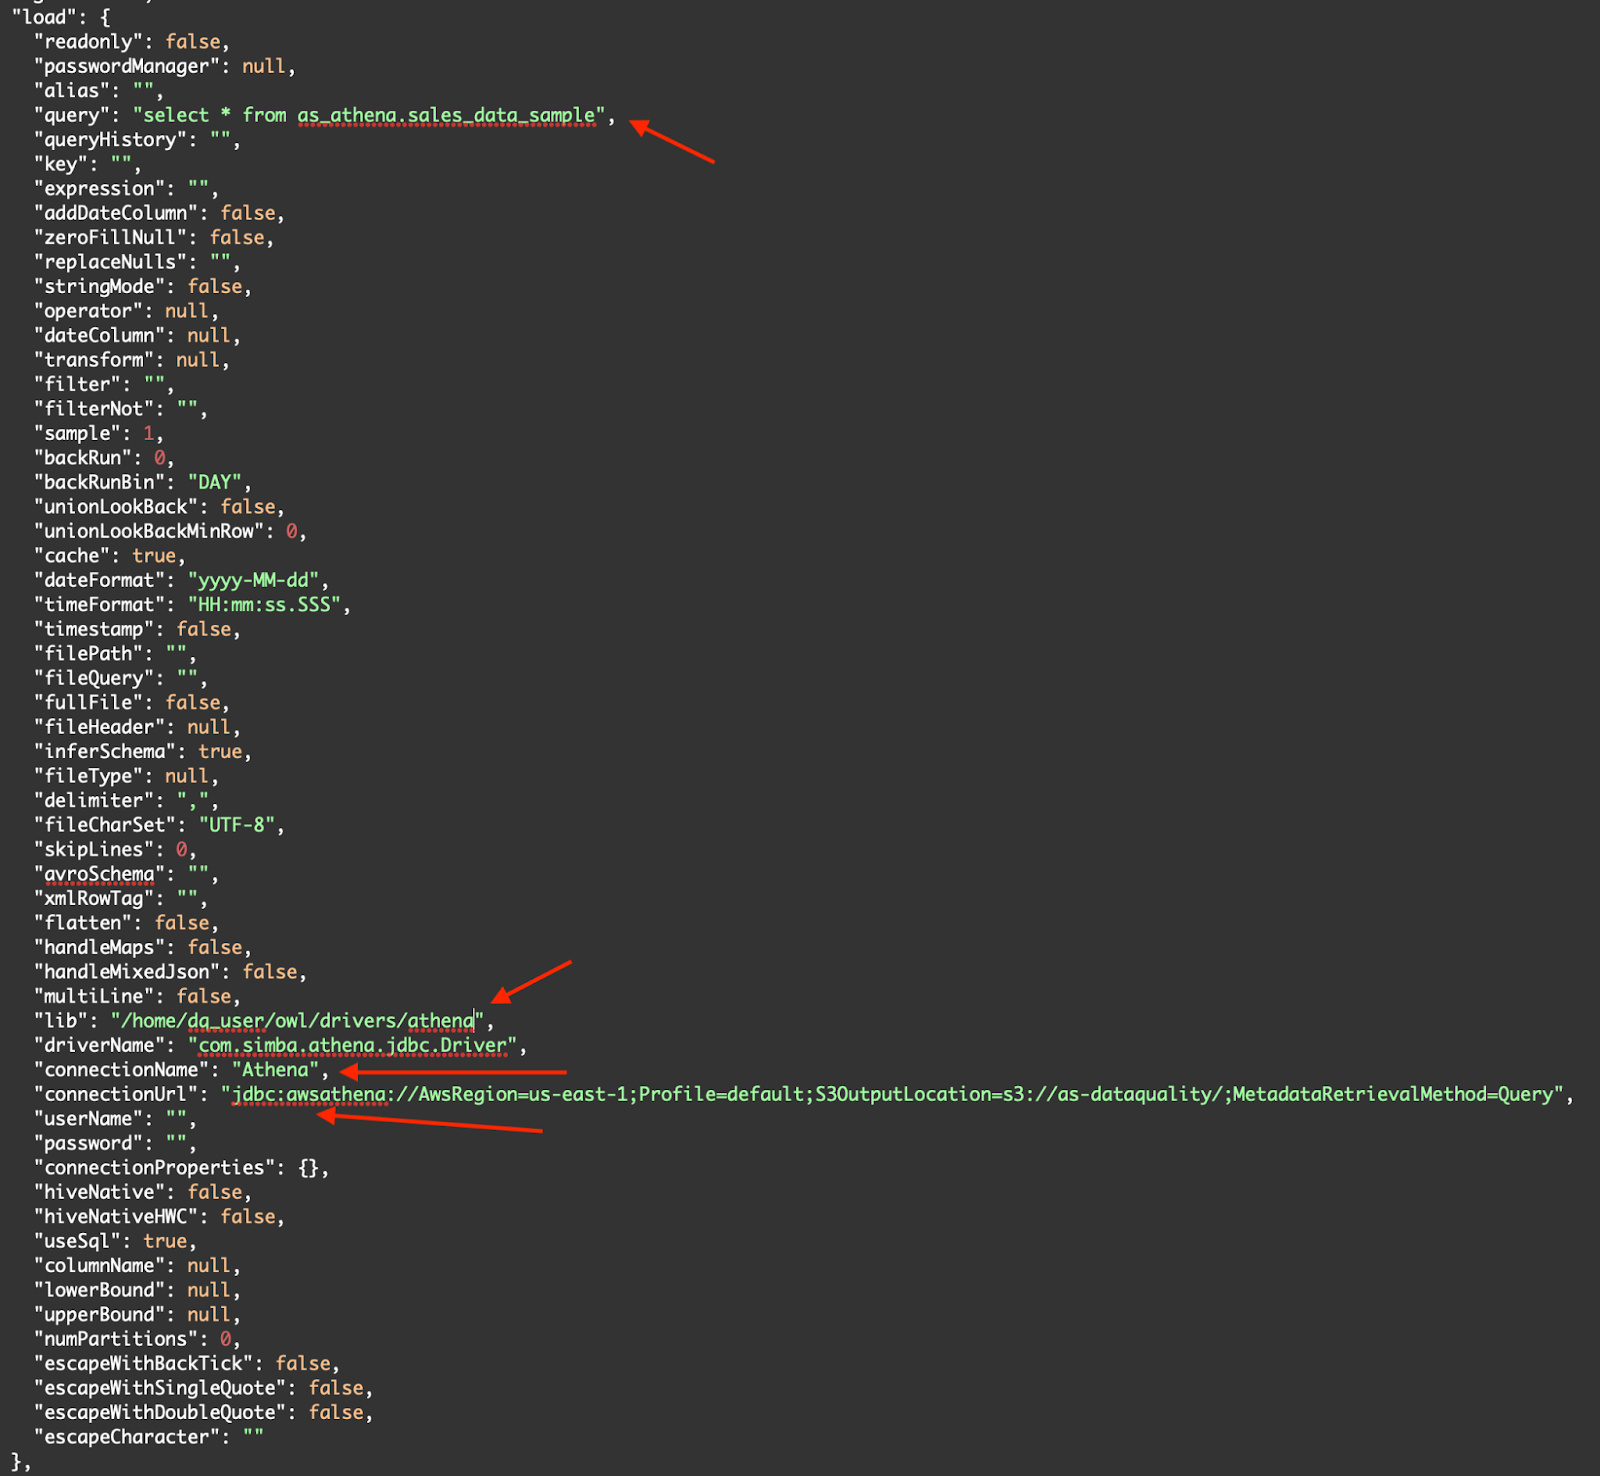
Now, we are going to configure the connection with Athena.
-
query -> The query to the table. In this case, you can see that you have to provide database.table in the query.
-
lib -> The path to the Athena driver.
-
connectionName -> The name of the connection that was created before.
-
connectionURL -> The URL that we have configured in the connection configuration.
Now, the information about the profile, outliers, sources … have to be provided, but we are going to keep it by default. After creating the dataset, we can navigate into DQ web app, modify everything and run the job again.
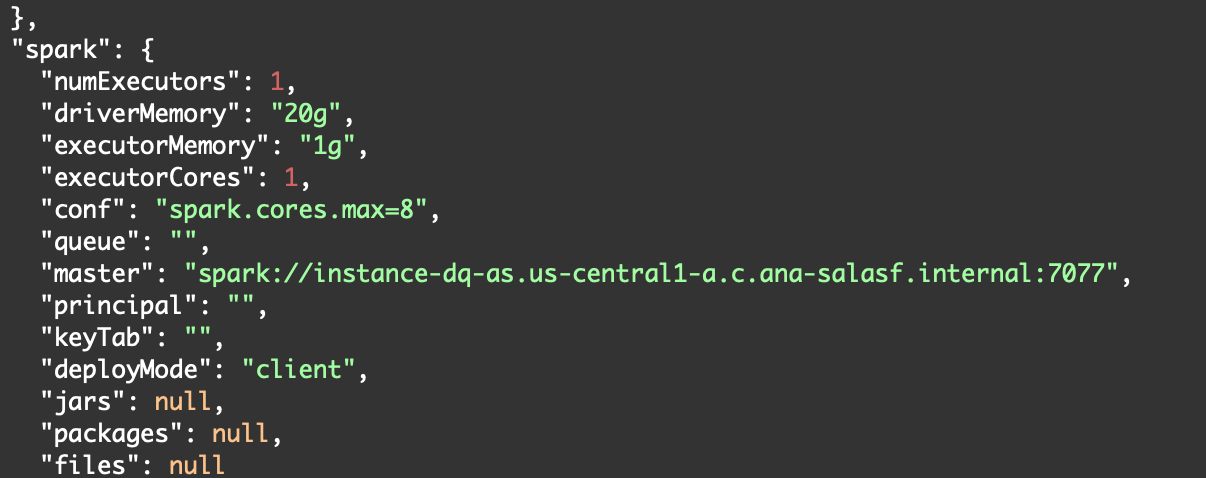
Change the master info, with your spark configuration.
- After that, copy the dataset configuration in the request body of the method “/v3/datasetDefs” and click on Execute.
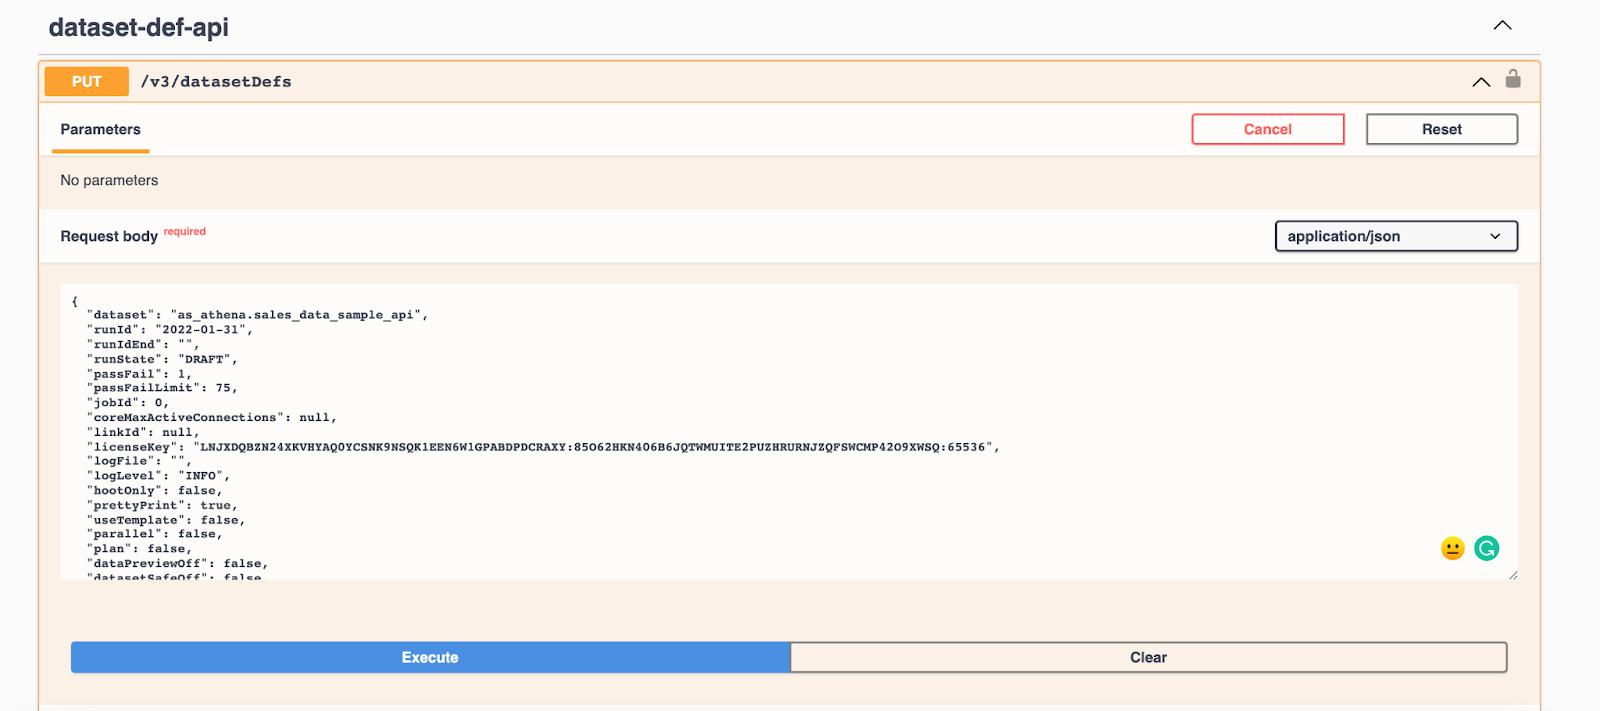
- Now, we have to run the job, if not, the dataset will not be shown in the DQ web app. To do that, go to “/v3/jobs/run”.
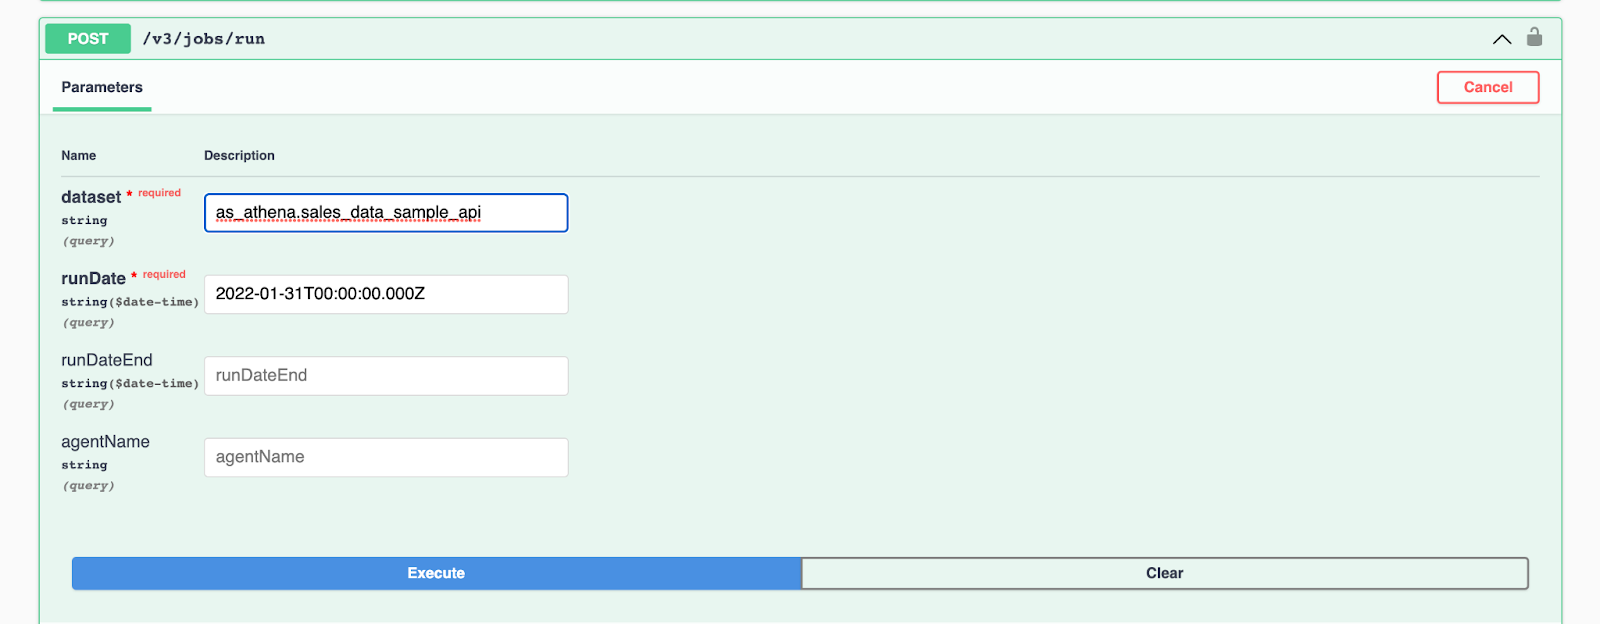
Provide the following parameters:
-
dataset: The name of the dataset.
-
runDate: you have to provide the date in this format: 2022-01-31T00:00:00.000Z
- And click on “Execute”, after that you can go to the job screen to see if your job is executing:

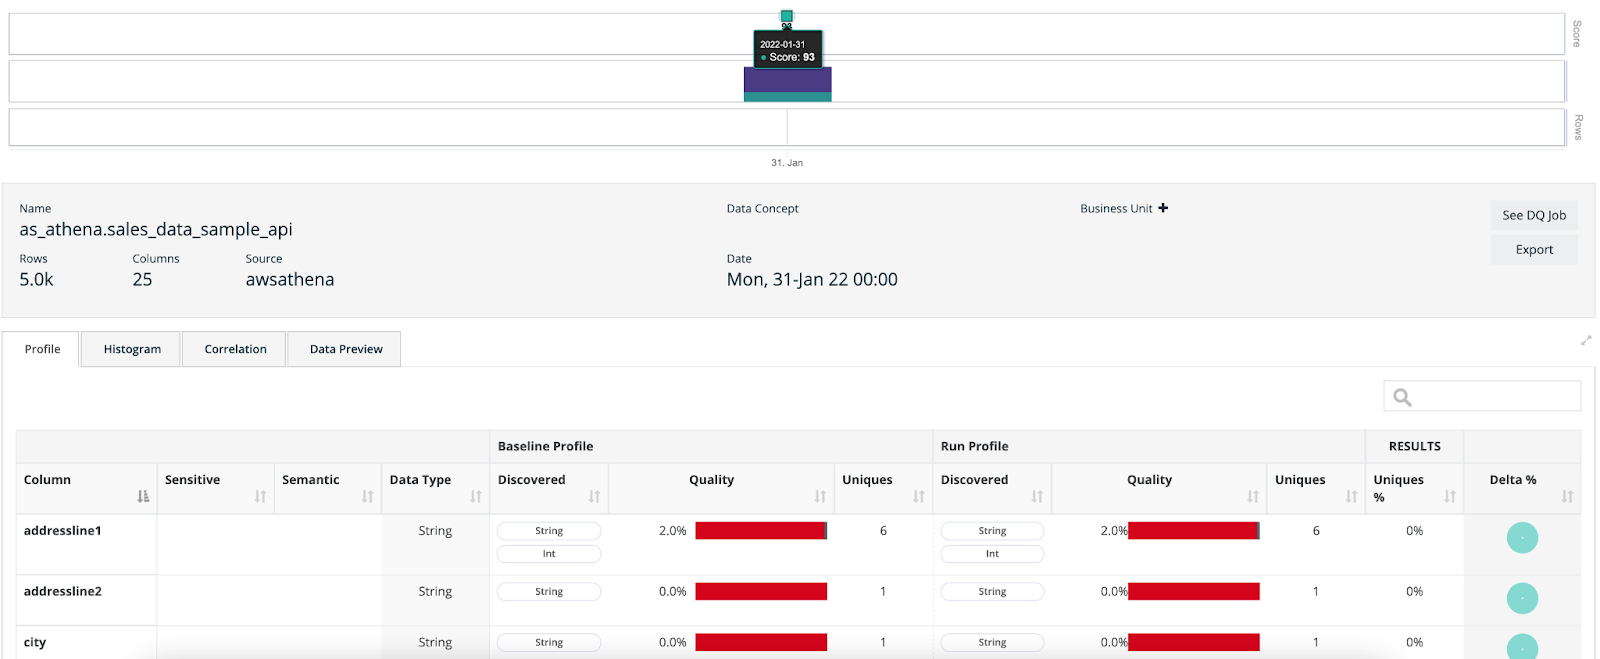
- Now, the dataset is available in the catalog and you can check the results, modify the job, create rules…