What is the meaning of the Collibra Data Quality dimensions?
Q: What is the meaning of the Collibra Data Quality dimensions?

A: There are many dimensions of Data Quality at Collibra:
-
Shapes: The actual shape of the field (eg. phone numbers in various countries) - Single column only.
-
Dupes: A) Exact duplications - indicate the columns that are checked. B) Fuzzy: William and Bill with the same address and phone number are also the same. There is a slider for percentage of closeness. Fuzzy matching is used to determine the possibility of a dupe (Levenshtein distance). Based on Spark Machine Learning library.
-
Schema: Changes in the schema
-
Record: # of records dropped or added (count) - if the use case says there should be between 1500 and 2500 - then this will flag if there’s a number outside that range
-
Source: Match to the single source of truth - this is accurate based on the lineage. Will detect differences.
-
Pattern: one or more columns together. States and sales-tax are different. Delaware has no tax - so if a tax-field in a Delaware sale is anything other than zero - that’s flagged. That could also be more than two columns.
-
Outliers: Outlier detection based on Interquartile Range (“IQR”). Two kinds: numerical and categorical (not a number) - 99% is numerical. bookstore: 99% of sales is books, but there might be other things (neck-pillow) - that would then be an outlier. Or high numbers of poor-selling items. Housing prices in the neighborhood… etc.
-
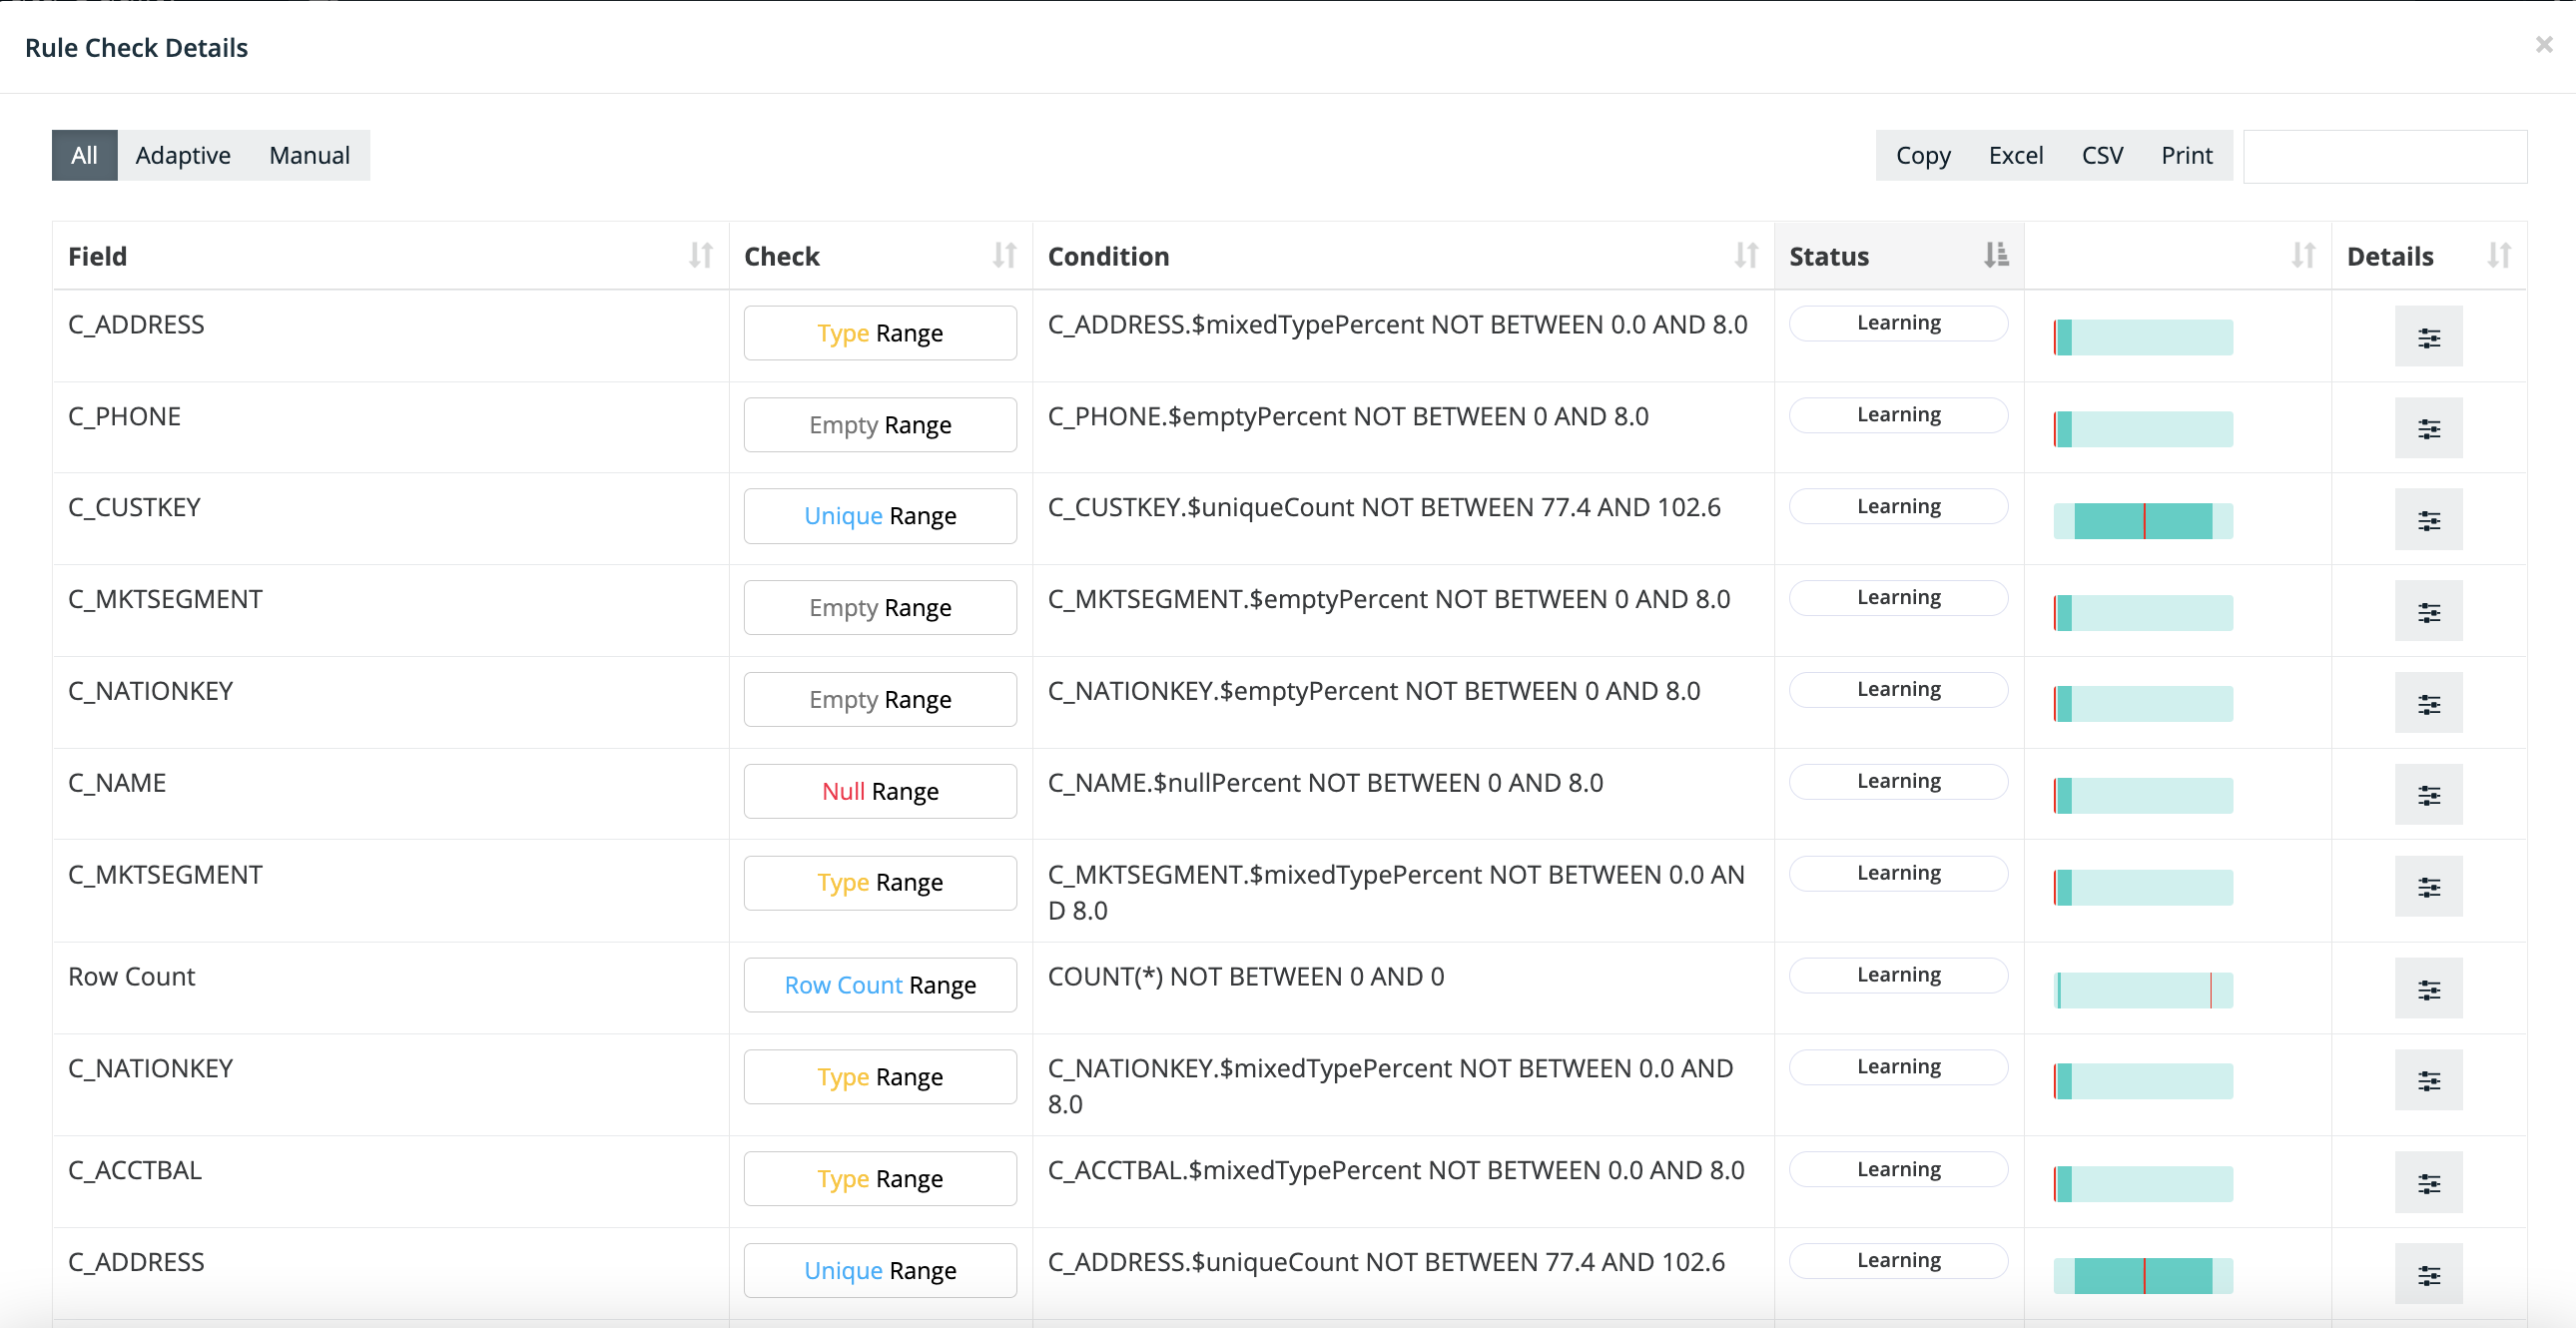
Rules: two main types - A) Adaptive or Automatic (no code required - they just run) See button [View AR].
-
B) User-defined Rules: can be anything including Spark SQL functions (which can be used - imported and already available)
-
Behavior: Behavioral Analytics which consists of the following factors:
- NULL values
- Empty values
- Cardinality
- Datatype shifting
- Row counts
- Load time
- Minimum Value
- Maximum Value
- Mean Value

